Note
Go to the end to download the full example code.
Introduction || Tensors || Autograd || Building Models || TensorBoard Support || Training Models || Model Understanding
Training with PyTorch#
Created On: Nov 30, 2021 | Last Updated: May 06, 2026 | Last Verified: Nov 05, 2024
Follow along with the video below or on youtube.
Introduction#
In past videos, we’ve discussed and demonstrated:
Building models with the neural network layers and functions of the torch.nn module
The mechanics of automated gradient computation, which is central to gradient-based model training
Using TensorBoard to visualize training progress and other activities
In this video, we’ll be adding some new tools to your inventory:
We’ll get familiar with the dataset and dataloader abstractions, and how they ease the process of feeding data to your model during a training loop
We’ll discuss specific loss functions and when to use them
We’ll look at PyTorch optimizers, which implement algorithms to adjust model weights based on the outcome of a loss function
Finally, we’ll pull all of these together and see a full PyTorch training loop in action.
Dataset and DataLoader#
The Dataset and DataLoader classes encapsulate the process of
pulling your data from storage and exposing it to your training loop in
batches.
The Dataset is responsible for accessing and processing single
instances of data.
The DataLoader pulls instances of data from the Dataset (either
automatically or with a sampler that you define), collects them in
batches, and returns them for consumption by your training loop. The
DataLoader works with all kinds of datasets, regardless of the type
of data they contain.
For this tutorial, we’ll be using the Fashion-MNIST dataset provided by
TorchVision. We use torchvision.transforms.v2.Normalize() to
zero-center and normalize the distribution of the image tile content,
and download both training and validation data splits.
import torch
import torchvision
from torchvision.transforms import v2

# PyTorch TensorBoard support
from torch.utils.tensorboard import SummaryWriter
from datetime import datetime


transform = v2.Compose([
    v2.ToImage(),
    v2.ToDtype(torch.float32, scale=True),
    v2.Normalize((0.5,), (0.5,))
])

# Create datasets for training & validation, download if necessary
training_set = torchvision.datasets.FashionMNIST('./data', train=True, transform=transform, download=True)
validation_set = torchvision.datasets.FashionMNIST('./data', train=False, transform=transform, download=True)

# Create data loaders for our datasets; shuffle for training, not for validation
training_loader = torch.utils.data.DataLoader(training_set, batch_size=4, shuffle=True)
validation_loader = torch.utils.data.DataLoader(validation_set, batch_size=4, shuffle=False)

# Class labels
classes = ('T-shirt/top', 'Trouser', 'Pullover', 'Dress', 'Coat',
        'Sandal', 'Shirt', 'Sneaker', 'Bag', 'Ankle Boot')

# Report split sizes
print(f'Training set has {len(training_set)} instances')
print(f'Validation set has {len(validation_set)} instances')
  0%|          | 0.00/26.4M [00:00<?, ?B/s]
  0%|          | 65.5k/26.4M [00:00<01:09, 377kB/s]
  1%|          | 197k/26.4M [00:00<00:44, 595kB/s]
  3%|▎         | 819k/26.4M [00:00<00:13, 1.94MB/s]
 13%|█▎        | 3.31M/26.4M [00:00<00:03, 6.78MB/s]
 35%|███▌      | 9.34M/26.4M [00:00<00:01, 16.7MB/s]
 59%|█████▉    | 15.6M/26.4M [00:01<00:00, 23.1MB/s]
 79%|███████▊  | 20.8M/26.4M [00:01<00:00, 29.4MB/s]
 93%|█████████▎| 24.6M/26.4M [00:01<00:00, 29.8MB/s]
100%|██████████| 26.4M/26.4M [00:01<00:00, 19.9MB/s]

  0%|          | 0.00/29.5k [00:00<?, ?B/s]
100%|██████████| 29.5k/29.5k [00:00<00:00, 336kB/s]

  0%|          | 0.00/4.42M [00:00<?, ?B/s]
  1%|▏         | 65.5k/4.42M [00:00<00:11, 374kB/s]
  5%|▌         | 229k/4.42M [00:00<00:05, 705kB/s]
 21%|██        | 918k/4.42M [00:00<00:01, 2.17MB/s]
 83%|████████▎ | 3.67M/4.42M [00:00<00:00, 7.53MB/s]
100%|██████████| 4.42M/4.42M [00:00<00:00, 6.30MB/s]

  0%|          | 0.00/5.15k [00:00<?, ?B/s]
100%|██████████| 5.15k/5.15k [00:00<00:00, 29.4MB/s]
Training set has 60000 instances
Validation set has 10000 instances
As always, let’s visualize the data as a sanity check:
import matplotlib.pyplot as plt
import numpy as np

# Helper function for inline image display
def matplotlib_imshow(img, one_channel=False):
    if one_channel:
        img = img.mean(dim=0)
    img = img / 2 + 0.5     # unnormalize
    npimg = img.numpy()
    if one_channel:
        plt.imshow(npimg, cmap="Greys")
    else:
        plt.imshow(np.transpose(npimg, (1, 2, 0)))

dataiter = iter(training_loader)
images, labels = next(dataiter)

# Create a grid from the images and show them
img_grid = torchvision.utils.make_grid(images)
matplotlib_imshow(img_grid, one_channel=True)
print('  '.join(classes[labels[j]] for j in range(4)))
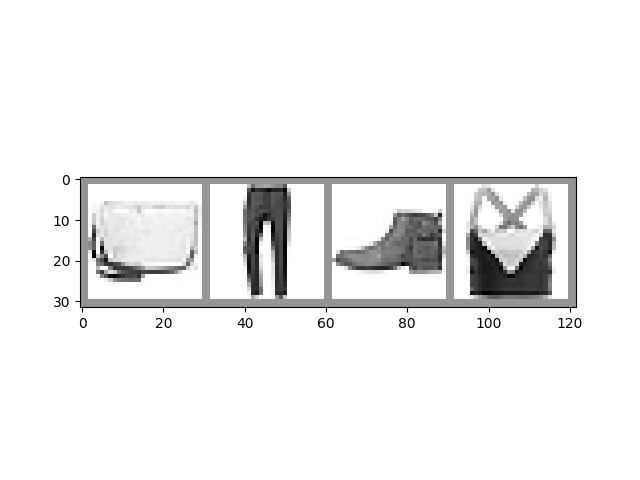
Coat Sandal Sandal Sandal
The Model#
The model we’ll use in this example is a variant of LeNet-5 - it should be familiar if you’ve watched the previous videos in this series.
import torch.nn as nn
import torch.nn.functional as F

# PyTorch models inherit from torch.nn.Module
class GarmentClassifier(nn.Module):
    def __init__(self):
        super().__init__()
        self.conv1 = nn.Conv2d(1, 6, 5)
        self.pool = nn.MaxPool2d(2, 2)
        self.conv2 = nn.Conv2d(6, 16, 5)
        self.fc1 = nn.Linear(16 * 4 * 4, 120)
        self.fc2 = nn.Linear(120, 84)
        self.fc3 = nn.Linear(84, 10)

    def forward(self, x):
        x = self.pool(F.relu(self.conv1(x)))
        x = self.pool(F.relu(self.conv2(x)))
        x = x.view(-1, 16 * 4 * 4)
        x = F.relu(self.fc1(x))
        x = F.relu(self.fc2(x))
        x = self.fc3(x)
        return x


model = GarmentClassifier()
Loss Function#
For this example, we’ll be using a cross-entropy loss. For demonstration purposes, we’ll create batches of dummy output and label values, run them through the loss function, and examine the result.
loss_fn = torch.nn.CrossEntropyLoss()

# NB: Loss functions expect data in batches, so we're creating batches of 4
# Represents the model's confidence in each of the 10 classes for a given input
dummy_outputs = torch.rand(4, 10)
# Represents the correct class among the 10 being tested
dummy_labels = torch.tensor([1, 5, 3, 7])

print(dummy_outputs)
print(dummy_labels)

loss = loss_fn(dummy_outputs, dummy_labels)
print(f'Total loss for this batch: {loss.item()}')
tensor([[0.7184, 0.1655, 0.1759, 0.9440, 0.0615, 0.0755, 0.8855, 0.9494, 0.3157,
         0.8053],
        [0.3399, 0.0763, 0.9391, 0.8384, 0.3507, 0.2258, 0.9778, 0.5391, 0.0336,
         0.4179],
        [0.4209, 0.6427, 0.0444, 0.6745, 0.9665, 0.4579, 0.9699, 0.6172, 0.0654,
         0.1907],
        [0.7417, 0.4447, 0.4362, 0.7119, 0.0766, 0.0033, 0.9300, 0.7900, 0.3409,
         0.8731]])
tensor([1, 5, 3, 7])
Total loss for this batch: 2.397796392440796
Optimizer#
For this example, we’ll be using simple stochastic gradient descent with momentum.
It can be instructive to try some variations on this optimization scheme:
Learning rate determines the size of the steps the optimizer takes. What does a different learning rate do to the your training results, in terms of accuracy and convergence time?
Momentum nudges the optimizer in the direction of strongest gradient over multiple steps. What does changing this value do to your results?
Try some different optimization algorithms, such as averaged SGD, Adagrad, or Adam. How do your results differ?
# Optimizers specified in the torch.optim package
optimizer = torch.optim.SGD(model.parameters(), lr=0.001, momentum=0.9)
The Training Loop#
Below, we have a function that performs one training epoch. It enumerates data from the DataLoader, and on each pass of the loop does the following:
Gets a batch of training data from the DataLoader
Zeros the optimizer’s gradients
Performs an inference - that is, gets predictions from the model for an input batch
Calculates the loss for that set of predictions vs. the labels on the dataset
Calculates the backward gradients over the learning weights
Tells the optimizer to perform one learning step - that is, adjust the model’s learning weights based on the observed gradients for this batch, according to the optimization algorithm we chose
It reports on the loss for every 1000 batches.
Finally, it reports the average per-batch loss for the last 1000 batches, for comparison with a validation run
def train_one_epoch(epoch_index, tb_writer):
    running_loss = 0.
    last_loss = 0.

    # Here, we use enumerate(training_loader) instead of
    # iter(training_loader) so that we can track the batch
    # index and do some intra-epoch reporting
    for i, data in enumerate(training_loader):
        # Every data instance is an input + label pair
        inputs, labels = data

        # Zero your gradients for every batch!
        optimizer.zero_grad()

        # Make predictions for this batch
        outputs = model(inputs)

        # Compute the loss and its gradients
        loss = loss_fn(outputs, labels)
        loss.backward()

        # Adjust learning weights
        optimizer.step()

        # Gather data and report
        running_loss += loss.item()
        if i % 1000 == 999:
            last_loss = running_loss / 1000 # loss per batch
            print(f'  batch {i + 1} loss: {last_loss}')
            tb_x = epoch_index * len(training_loader) + i + 1
            tb_writer.add_scalar('Loss/train', last_loss, tb_x)
            running_loss = 0.

    return last_loss
Per-Epoch Activity#
There are a couple of things we’ll want to do once per epoch:
Perform validation by checking our relative loss on a set of data that was not used for training, and report this
Save a copy of the model
Here, we’ll do our reporting in TensorBoard. This will require going to the command line to start TensorBoard, and opening it in another browser tab.
# Initializing in a separate cell so we can easily add more epochs to the same run
timestamp = datetime.now().strftime('%Y%m%d_%H%M%S')
writer = SummaryWriter(f'runs/fashion_trainer_{timestamp}')
epoch_number = 0

EPOCHS = 5

best_vloss = 1_000_000.

for epoch in range(EPOCHS):
    print(f'EPOCH {epoch_number + 1}:')

    # Make sure gradient tracking is on, and do a pass over the data
    model.train(True)
    avg_loss = train_one_epoch(epoch_number, writer)


    running_vloss = 0.0
    # Set the model to evaluation mode, disabling dropout and using population
    # statistics for batch normalization.
    model.eval()

    # Disable gradient computation and reduce memory consumption.
    with torch.no_grad():
        for i, vdata in enumerate(validation_loader):
            vinputs, vlabels = vdata
            voutputs = model(vinputs)
            vloss = loss_fn(voutputs, vlabels)
            running_vloss += vloss

    avg_vloss = running_vloss / (i + 1)
    print(f'LOSS train {avg_loss} valid {avg_vloss}')

    # Log the running loss averaged per batch
    # for both training and validation
    writer.add_scalars('Training vs. Validation Loss',
                    { 'Training' : avg_loss, 'Validation' : avg_vloss },
                    epoch_number + 1)
    writer.flush()

    # Track best performance, and save the model's state
    if avg_vloss < best_vloss:
        best_vloss = avg_vloss
        model_path = f'model_{timestamp}_{epoch_number}'
        torch.save(model.state_dict(), model_path)

    epoch_number += 1
EPOCH 1:
  batch 1000 loss: 1.8230471438318492
  batch 2000 loss: 0.8375185116929933
  batch 3000 loss: 0.7115338755524717
  batch 4000 loss: 0.6573117403960786
  batch 5000 loss: 0.6209670089315623
  batch 6000 loss: 0.5607881091802847
  batch 7000 loss: 0.5422997672590427
  batch 8000 loss: 0.5099639085128438
  batch 9000 loss: 0.4706088437454891
  batch 10000 loss: 0.47662662993185223
  batch 11000 loss: 0.43914827322855127
  batch 12000 loss: 0.44098631772678343
  batch 13000 loss: 0.4382273501467425
  batch 14000 loss: 0.4056500417924253
  batch 15000 loss: 0.40536462246463634
LOSS train 0.40536462246463634 valid 0.4013791084289551
EPOCH 2:
  batch 1000 loss: 0.3762514235776616
  batch 2000 loss: 0.3937058314481401
  batch 3000 loss: 0.39485749913868495
  batch 4000 loss: 0.38010101368033794
  batch 5000 loss: 0.37188759240991204
  batch 6000 loss: 0.3891893863150617
  batch 7000 loss: 0.360356874473393
  batch 8000 loss: 0.3609640828907141
  batch 9000 loss: 0.35730807226669276
  batch 10000 loss: 0.37304390245111424
  batch 11000 loss: 0.3474621950163273
  batch 12000 loss: 0.36097339089664454
  batch 13000 loss: 0.3481557150188637
  batch 14000 loss: 0.35082161480365903
  batch 15000 loss: 0.34660449660123416
LOSS train 0.34660449660123416 valid 0.342926561832428
EPOCH 3:
  batch 1000 loss: 0.34077180782370853
  batch 2000 loss: 0.32160352693719324
  batch 3000 loss: 0.319566358641925
  batch 4000 loss: 0.30716779435871283
  batch 5000 loss: 0.3332792193550704
  batch 6000 loss: 0.33021468782116425
  batch 7000 loss: 0.3058661087425244
  batch 8000 loss: 0.3385994797748517
  batch 9000 loss: 0.3296817681888351
  batch 10000 loss: 0.3073792772270463
  batch 11000 loss: 0.31018127239873866
  batch 12000 loss: 0.31221817575942257
  batch 13000 loss: 0.31901111860950915
  batch 14000 loss: 0.3086965267888809
  batch 15000 loss: 0.3154105148709205
LOSS train 0.3154105148709205 valid 0.3385365605354309
EPOCH 4:
  batch 1000 loss: 0.30659144166194163
  batch 2000 loss: 0.2952819596636691
  batch 3000 loss: 0.2960424669934364
  batch 4000 loss: 0.29663852632614907
  batch 5000 loss: 0.3037887311850482
  batch 6000 loss: 0.28997817742497867
  batch 7000 loss: 0.298865061565255
  batch 8000 loss: 0.28320872366234834
  batch 9000 loss: 0.29563375441916284
  batch 10000 loss: 0.2953392083346989
  batch 11000 loss: 0.2870367189937315
  batch 12000 loss: 0.2867740854976546
  batch 13000 loss: 0.29752143946784415
  batch 14000 loss: 0.2652928286748011
  batch 15000 loss: 0.29993774948154894
LOSS train 0.29993774948154894 valid 0.36667296290397644
EPOCH 5:
  batch 1000 loss: 0.260153538092909
  batch 2000 loss: 0.27928893542967126
  batch 3000 loss: 0.28576525647442397
  batch 4000 loss: 0.29414563723226456
  batch 5000 loss: 0.26689724322042596
  batch 6000 loss: 0.2731887277782225
  batch 7000 loss: 0.2685873210356185
  batch 8000 loss: 0.2599401998279336
  batch 9000 loss: 0.28437775208817767
  batch 10000 loss: 0.2660251740928943
  batch 11000 loss: 0.2862967532668554
  batch 12000 loss: 0.26831272712036297
  batch 13000 loss: 0.281643627233163
  batch 14000 loss: 0.27631163845700574
  batch 15000 loss: 0.2788718156504665
LOSS train 0.2788718156504665 valid 0.3159927427768707
To load a saved version of the model:
saved_model = GarmentClassifier()
saved_model.load_state_dict(torch.load(PATH))
Once you’ve loaded the model, it’s ready for whatever you need it for - more training, inference, or analysis.
Note that if your model has constructor parameters that affect model structure, you’ll need to provide them and configure the model identically to the state in which it was saved.
Other Resources#
Docs on the data utilities, including Dataset and DataLoader, at pytorch.org
A note on the use of pinned memory for GPU training
Documentation on the datasets available in TorchVision, TorchText, and TorchAudio
Documentation on the loss functions available in PyTorch
Documentation on the torch.optim package, which includes optimizers and related tools, such as learning rate scheduling
A detailed tutorial on saving and loading models
The Tutorials section of pytorch.org contains tutorials on a broad variety of training tasks, including classification in different domains, generative adversarial networks, reinforcement learning, and more
Total running time of the script: (3 minutes 22.013 seconds)