ExecuTorch Native#
Note
ExecuTorch Native is experimental. The Python API, the .ptn format, and
operator coverage may change.
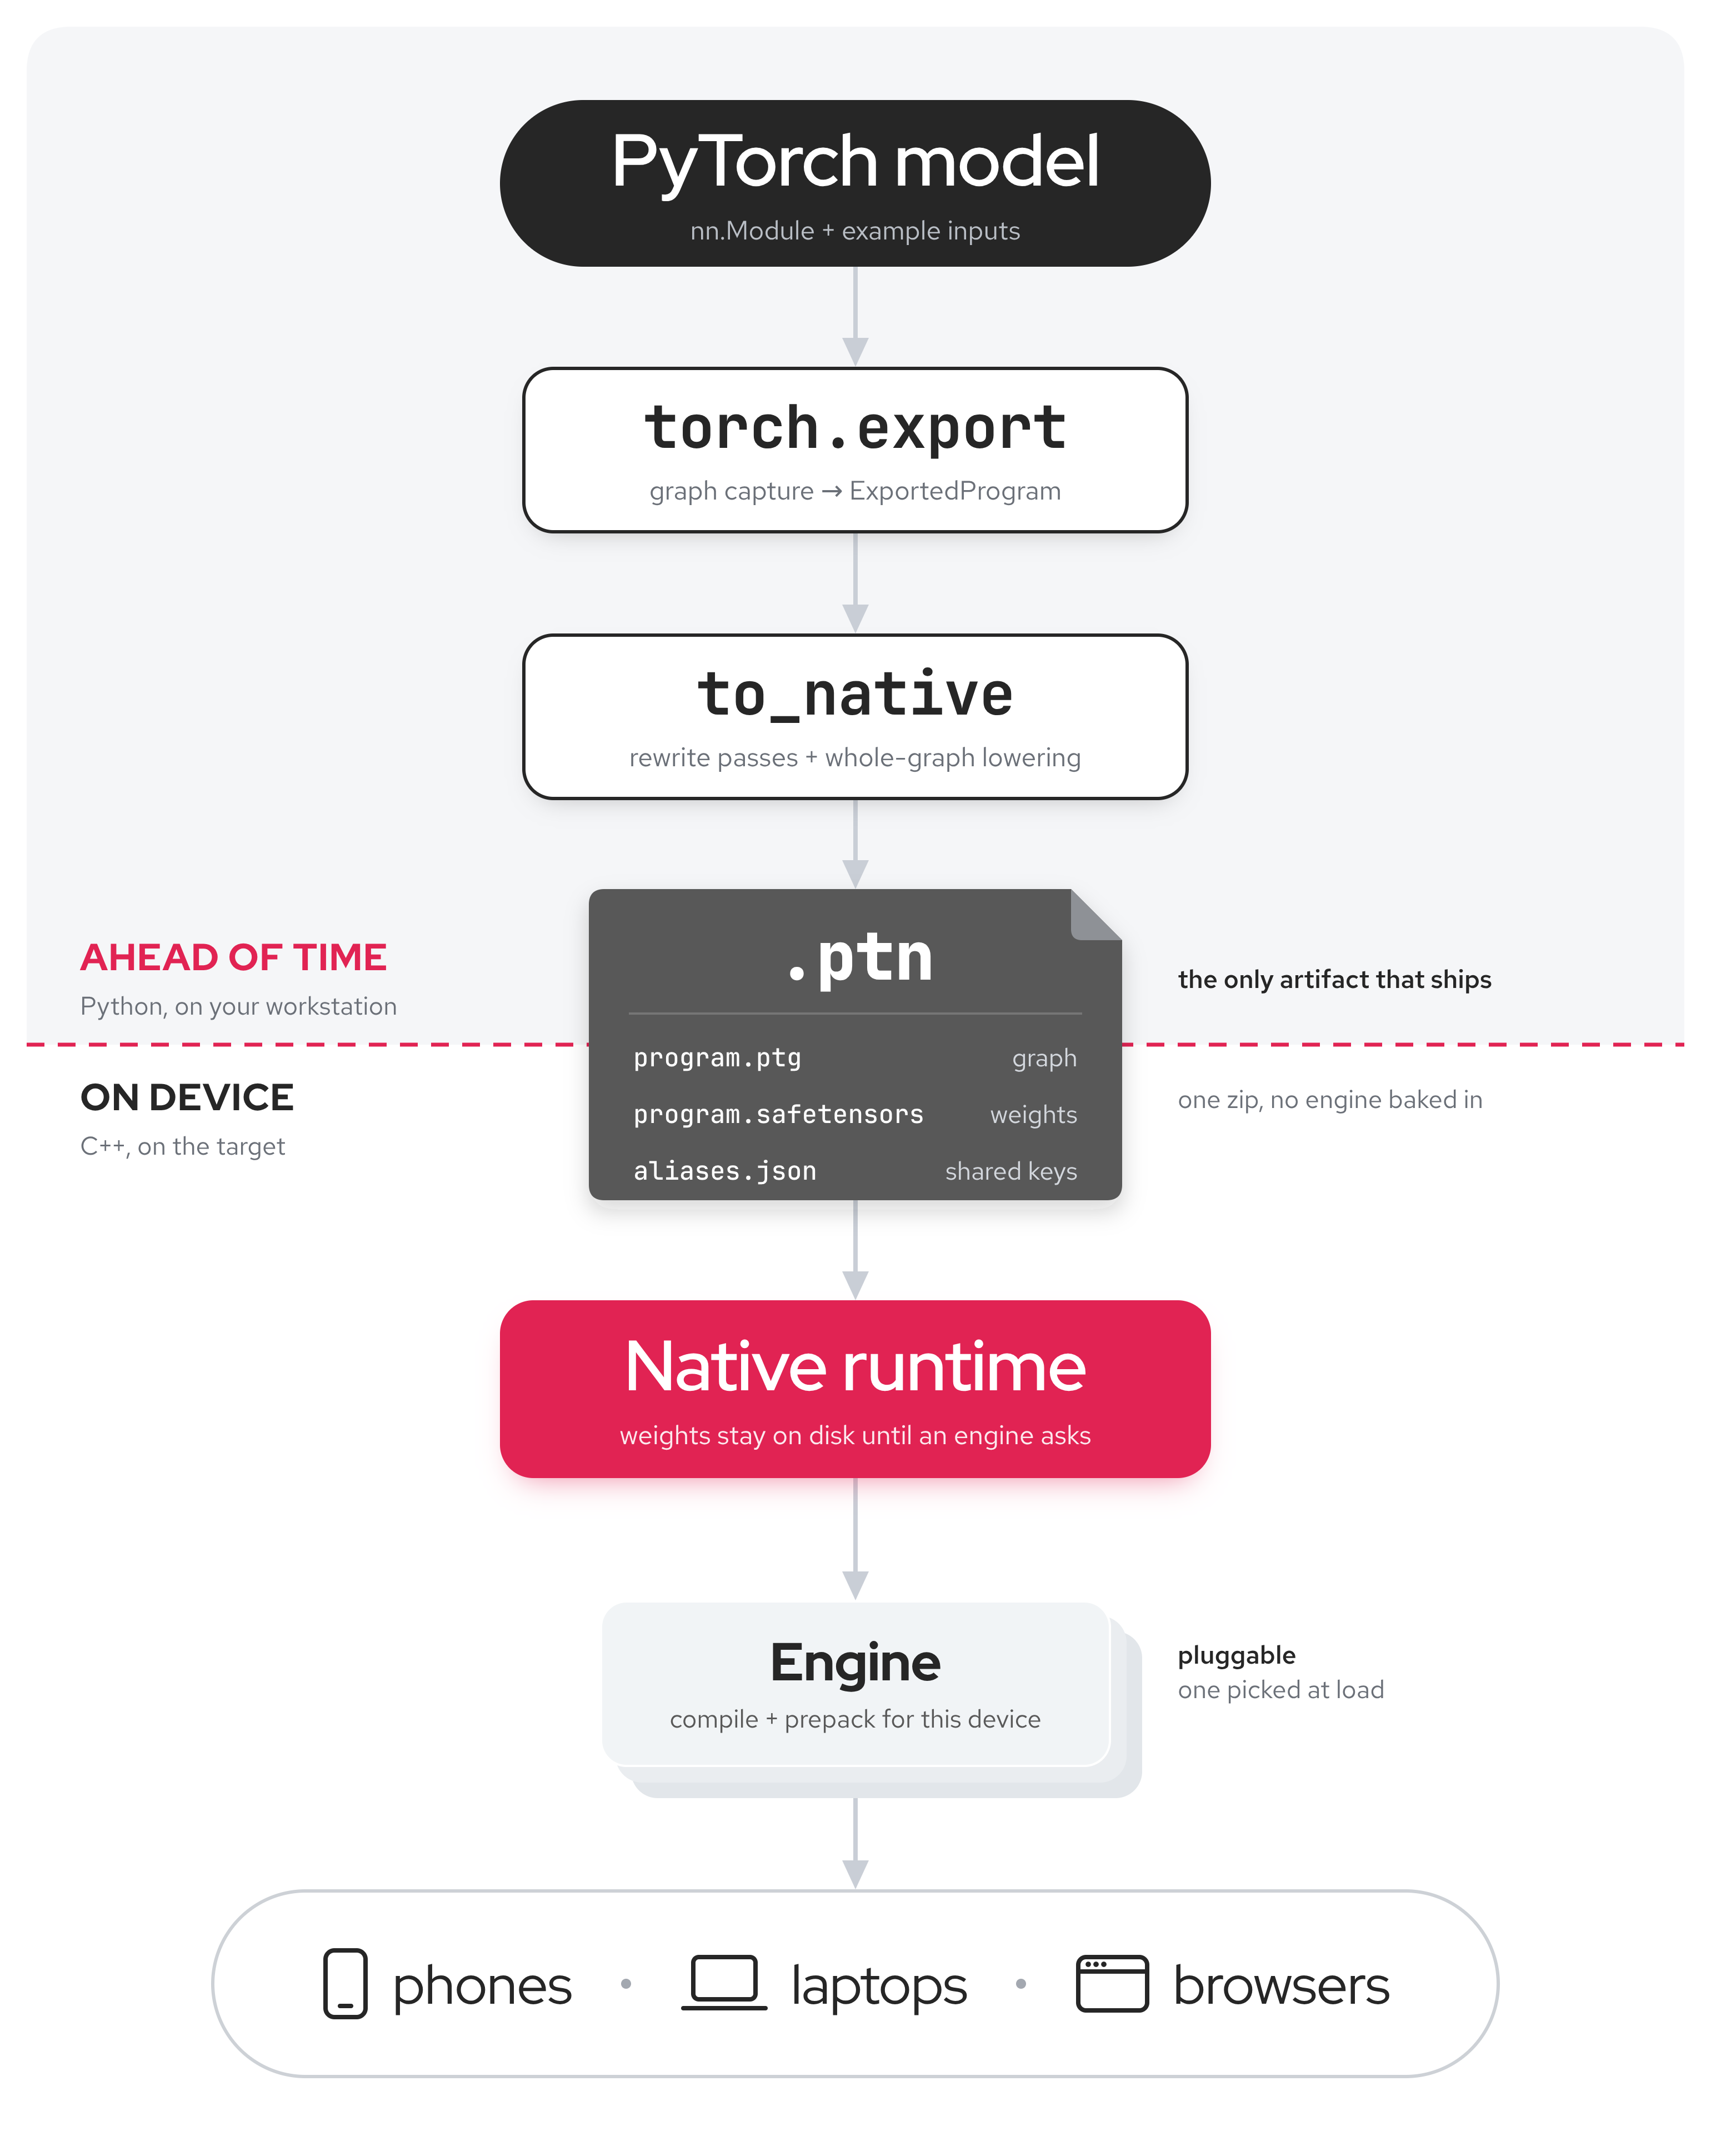
ExecuTorch Native lowers a PyTorch model to a single .ptn file and runs it on
one of several engines. In a .pte, delegates lower the graph ahead of time for
specific backends. A .ptn keeps the whole graph without backend-specific
information, and each engine lowers it when compiling a method.
.pte:  export -> [quantize] -> to_edge -> to_backend -> to_executorch -> .pte (+ .ptd)
.ptn:  export -> [quantize] -> to_native -> .ptn
Export#
import torch
from executorch.exir.native import to_native

ep = torch.export.export(model, example_inputs)
to_native(ep).save("model.ptn")

# Several methods in one file.
to_native({"forward": ep_forward, "prefill": ep_prefill}).save("model.ptn")
The partitioner accepts core ATen ops plus linear, matmul, addmm,
scaled_dot_product_attention, rms_norm, native::rope, and TorchAO affine
quantize/dequantize ops. TorchAO int4 group-wise weights of linear and
embedding, and GGUF k-quant weights from executorch.extension.llm.export.gguf,
are stored packed with their scheme in tensor metadata. Each method must lower
wholly to one delegate; to_native raises otherwise.
A .ptn is an uncompressed zip with fixed entry names:
Entry |
Contents |
|---|---|
|
Methods as graphs; FlatBuffer defined by |
|
Constants. Byte-identical immutable tensors are stored once. |
|
Deduplicated key to owner key; present only when needed. |
Runtime#
The C++ runtime reads a .ptn into an in-memory graph and hands each method to
an engine through the interfaces in
Engine.h.
EngineHost: process-wide device resources.EngineContext: state for one loaded program, including mutable buffers.EngineExecutable: one compiled method (set_input,execute,get_output).
An engine rejects a method whose semantics it cannot fully honor.
Engine |
Notes |
|---|---|
Vulkan |
Builds on the ET-VK |
ggml |
CPU, CUDA, HIP, and Metal variants. |
The runtime currently builds only with Meta’s internal Buck setup; there is no open-source build yet.
The source is in
exir/native/ and
backends/native/.