TensorDictBase.consolidate#
- TensorDictBase.consolidate(filename: Path | str | None = None, *, num_threads=0, device: device | None = None, non_blocking: bool = False, inplace: bool = False, return_early: bool = False, use_buffer: bool = False, share_memory: bool = False, pin_memory: bool = False, metadata: bool = False) None#
Copies all the leaves into one contiguous storage, and returns a tensordict of views of it.
A consolidated tensordict pickles and moves between devices faster, because its leaves are one block of memory:
to(),pickle,send()andbroadcast()move that block in one copy. The result is locked (see Locking and temporary changes): you can write into its leaves in place, but you cannot add or remove entries.If the tensordict is already consolidated,
selfis returned and the other arguments are ignored, exceptpin_memory=True: a storage on the CPU that is not pinned is then copied into a pinned one, and a new tensordict is returned, unlessfilename,inplace=True,return_early=Truewithnum_threads > 1or adeviceother than the CPU is given, or no accelerator is available. Afilenameother than its own file writes nothing and emits aUserWarning:td.contiguous().consolidate(filename=other)writes a new file. Adeviceother than the one of the storage, andshare_memory=Truewith a storage that is not in shared memory, are ignored with aFutureWarning. Starting with TensorDict 0.17, the default will change to honouring them, as for a tensordict that is not consolidated: the call will return a new consolidated tensordict.td.contiguous().consolidate(...)gives that result now.- Parameters:
filename (str or Path, optional) – a file to use as the storage. The leaves are views into a memory map of the file, and the metadata is written after them, so that
from_consolidated()can read the file back. An existing file is written in place, unless it is larger than the new one anduse_buffer=False: it is then replaced by a new file, and the tensordicts that map the old file keep their data. Defaults toNone, which keeps the storage in memory.- Keyword Arguments:
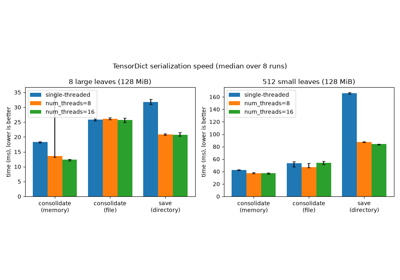
num_threads (int, optional) – the number of threads that copy the leaves into the storage, by chunks of about equal size. When
filenameis given,return_early=Falseand all the leaves are on the CPU, one copy is faster andnum_threadsis ignored. Defaults to0, which copies in the calling thread.device (device, str or int, optional) – the device of the storage. Exclusive with
filename, unless it is"cpu". Defaults toNone, which uses the device of the tensordict, or the CPU if it has none.non_blocking (bool, optional) – if
True, copies between devices can run asynchronously with respect to the host. Defaults toFalse.inplace (bool, optional) – if
True, the leaves of the tensordict are replaced by the views, andselfis returned. Defaults toFalse.return_early (bool, optional) – if
Trueandnum_threads > 1, returns aTensorDictFutureat once, while the threads copy the leaves:future.result()waits for them and returns the tensordict. Not supported withuse_buffer=Trueornon_blocking=True. Defaults toFalse.use_buffer (bool, optional) – if
Trueandfilenameis given, the leaves are copied into a buffer in shared memory, which is written to the file at the end. This can be faster on a remote file system (for example NFS). In-place writes into the leaves then do not reach the file. Defaults toFalse.share_memory (bool, optional) – if
True, the storage is placed in shared memory. Defaults toFalse.pin_memory (bool, optional) – if
True, the storage is placed in pinned memory. Defaults toFalse.metadata (bool, optional) – if
True, the structure of the tensordict is stored with the storage, which changes how the result is pickled;send()andinit_remote()use it. It is always stored whenfilenameis given. Defaults toFalse.
- Returns:
A consolidated tensordict,
selfifinplace=True, or aTensorDictFutureof it ifreturn_early=Trueandnum_threads > 1.
Note
The file written with
filenameholds the batch sizes and names at the time of the call. Settingbatch_sizeornameson the result later does not change the file: callconsolidate(filename=filename)again on the result to write them. Likewise, a pickle of the result is rebuilt from metadata recorded here: setting the batch size of a nested tensordict, as intd["nested"].batch_size = ..., may not update it untilconsolidate()is called again.Examples
>>> import pickle
>>> import torch
>>> from tensordict import TensorDict
>>> data = TensorDict({"a": torch.zeros(()), "b": {"c": torch.zeros(())}})
>>> data_consolidated = data.consolidate()
>>> # All the leaves share one storage.
>>> assert torch.tensor([
...     v.untyped_storage().data_ptr() for v in data_consolidated.values(True, True)
... ]).unique().numel() == 1
>>> data_consolidated.is_consolidated(), data_consolidated.is_locked
(True, True)
>>> # A consolidated tensordict pickles as one buffer.
>>> restored = pickle.loads(pickle.dumps(data_consolidated))
>>> (restored == data).all()
True
Every tensordict class and every tensorclass has this method. For the other methods, see Methods by task.