TensorDictBase.load_memmap#
- classmethod TensorDictBase.load_memmap(prefix: str | Path, device: device | None = None, non_blocking: bool = False, *, out: TensorDictBase | None = None, robust_key: bool | None = True, subpath: NestedKey | None = None, mode: str | None = None, num_threads: int = 0, allow_pickle: bool | None = None) Self#
Loads a memory-mapped tensordict from disk.
- Parameters:
prefix (str or Path to folder) – the path to the folder where the saved tensordict should be fetched, or the path to a memmap archive file written through
save(..., archive=True)/ a".tdz"prefix (or packed withpack_memmap()). Archives are memory-mapped once and every leaf is exposed as a zero-copy view into the mapping: only the pages of the leaves that are actually accessed are read from disk. Unlike directory-backed tensordicts, in-place writes to the leaves of an archive-loaded tensordict do not propagate to the file by default (seemode).device (device or equivalent, optional) – if provided, the data will be asynchronously cast to that device. Supports “meta” device, in which case the data isn’t loaded but a set of empty “meta” tensors are created. This is useful to get a sense of the total model size and structure without actually opening any file.
non_blocking (bool, optional) – if
True, synchronize won’t be called after loading tensors on device. Defaults toFalse.out (TensorDictBase, optional) – optional tensordict where the data should be loaded. Its nested containers are reused, but its leaves are rebound to the loaded tensors, so their storage is not reused. Keys of
outthat are missing from the saved data are removed. Ifouthas a device, the data is loaded on it, and a differentdeviceraises aValueError. To write the data into the preallocated storage ofout, useout.update_(TensorDict.load_memmap(prefix, device=device))instead.robust_key (bool, optional) – if
True(default), expects robust key encoding was used when saving and decodes filenames accordingly. IfFalse, uses legacy behavior. IfNone, uses the default robust behavior.subpath (NestedKey or str path, optional) – the location of a nested tensordict to load, as a nested key (e.g.
("module", "0"), with arbitrary nesting allowed as usual) or as a"/"-separated string path (e.g."module/0"). Only that subtree is loaded. Works both for directories (equivalent to appending the path toprefix) and for archives. A nested key reaches the entries of a saved tensorclass asobj.get(key)does, without its_tensordictlevel.mode (str, optional) – how the files are memory-mapped. With
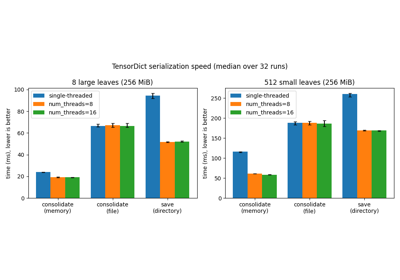
"r", the mapping is copy-on-write: in-place writes to the leaves stay in memory. They reach the files only if the tensordict is saved there, andmemmap_()without a prefix does not write back toprefix. With"r+", the mapping is shared: in-place writes propagate to the files, and a file that is not writable raises aPermissionError. Defaults toNone, which maps archives as with"r", and each file of a directory as with"r+"if the process can write it, as with"r"otherwise. Prefer"r"for data that is only read: on some network file systems (e.g. Lustre), page faults on a shared writable mapping take write locks, so readers on different nodes block each other. On Linux, copy-on-write mappings count against the memory commit limit, so a file larger than the available RAM and swap can fail to map with"r". With archives,"r+"requires uncompressed, aligned tensor payloads (i.e. archives written by tensordict withoutcompression) and is not available for nested-tensor leaves. In-place writes do not update the per-entry CRC-32 stored by the zip format;load_memmap()ignores checksums, but callrefresh_archive_checksums()before handing a modified archive to tools that verify them (unzip,unpack_memmap(), …).num_threads (int, optional) – number of threads used to decompress the leaves of a compressed archive (deflate entries are inflated in parallel, which scales nearly linearly). Without compression, loading is a metadata-only operation and this argument has no effect. Defaults to
0(sequential).allow_pickle (bool, optional) – whether pickled non-tensor fields may be loaded. Pickle can execute arbitrary code, so pass
Trueonly for data from a trusted source andFalsefor untrusted data. In TensorDict 0.14 and 0.15, omitting this option loads pickle with aFutureWarning; the default will change toFalsein 0.16. Saves without a pickle sidecar do not require this option.
Examples
>>> import torch
>>> from tensordict import TensorDict
>>> td = TensorDict.fromkeys(["a", "b", "c", ("nested", "e")], 0)
>>> _ = td.memmap("./saved_td")
>>> td_load = TensorDict.load_memmap("./saved_td")
>>> assert (td == td_load).all()
This method also allows loading nested tensordicts.
Examples
>>> nested = TensorDict.load_memmap("./saved_td/nested")
>>> assert nested["e"] == 0
A tensordict can also be loaded on “meta” device or, alternatively, as a fake tensor.
Examples
>>> import tempfile
>>> td = TensorDict({"a": torch.zeros(()), "b": {"c": torch.zeros(())}})
>>> with tempfile.TemporaryDirectory() as path:
...     _ = td.save(path)
...     td_load = TensorDict.load_memmap(path, device="meta")
...     print("meta:", td_load)
...     from torch._subclasses import FakeTensorMode
...     with FakeTensorMode():
...         td_load = TensorDict.load_memmap(path)
...         print("fake:", td_load)
meta: TensorDict(
    fields={
        a: Tensor(shape=torch.Size([]), device=meta, dtype=torch.float32, is_shared=False),
        b: TensorDict(
            fields={
                c: Tensor(shape=torch.Size([]), device=meta, dtype=torch.float32, is_shared=False)},
            batch_size=torch.Size([]),
            device=meta,
            is_shared=False)},
    batch_size=torch.Size([]),
    device=meta,
    is_shared=False)
fake: TensorDict(
    fields={
        a: FakeTensor(shape=torch.Size([]), device=cpu, dtype=torch.float32, is_shared=False),
        b: TensorDict(
            fields={
                c: FakeTensor(shape=torch.Size([]), device=cpu, dtype=torch.float32, is_shared=False)},
            batch_size=torch.Size([]),
            device=cpu,
            is_shared=False)},
    batch_size=torch.Size([]),
    device=cpu,
    is_shared=False)
Every tensordict class and every tensorclass has this method. For the other methods, see Methods by task.